projects
Which State Should Prediction Read?
2026Sole-author paper, under review at ICLR 2027. Reached a FLOP-matched Transformer’s loss on 2.1× fewer tokens and ended 0.064 nats/token lower after 20B tokens by designing Sequential, a final-state-read architecture, from these ablations (92M non-embedding params).
github.com/RyanKim17920/mechanistic-spsQwen3.6-27B ExpThink
2026Cut thinking tokens 52% in-domain / 34% OOD and truncation 6.0%→2.6% while mean OOD accuracy rose 84%→86% by post-training Qwen3.6-27B with a length-adjusted GRPO reward.
huggingface.co/ryankim17920/qwen3p6-27b-expthink-step60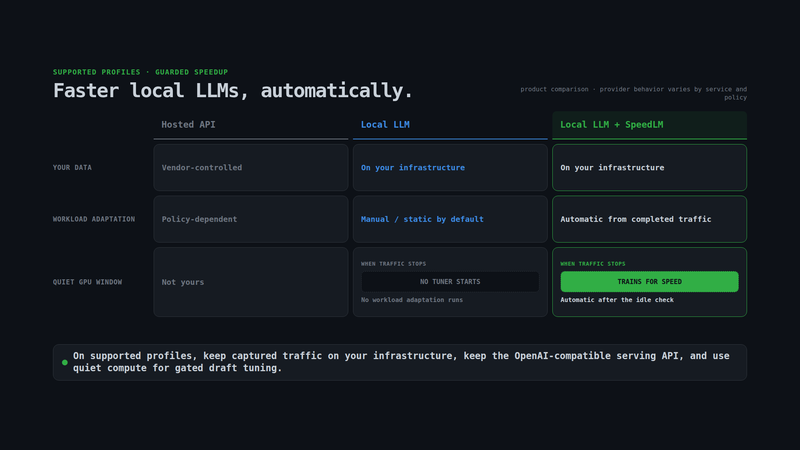
speedLM
2026Built a custom vLLM server that fine-tunes EAGLE-3 draft models on captured local traffic during idle GPU time. Raised tokens accepted per verification step 13.4% over the stock draft on held-out Qwen3-8B data.
github.com/RyanKim17920/speedlm
microDINOv3
2026DINOv3 in dependency-free pure Python — hand-written reverse-mode autograd and ViT, EMA teacher-student distillation, DINO + iBOT objectives, KoLeo regularization, axial RoPE with register tokens, and Gram anchoring.
github.com/RyanKim17920/microDINOv3
DeepMoE Reproduction
2024PyTorch reproduction of "Deep Mixture of Experts via Shallow Embedding," recovering the paper's accuracy-vs-compute tradeoff on CIFAR-10.
github.com/RyanKim17920/Deep-Mixture-of-Experts-via-Shallow-EmbeddingSPECTRA
2026Raised mean PathoROB robustness 0.726→0.891 and improved downstream AUC across 7 pathology foundation models (first-author paper, accepted at a NeurIPS 2026 workshop).
openreview.net/forum?id=Gs7BZ9XI3rLLM Autoresearch Agent (NanoPath)
2026Drove 37% of the gain over baseline on NanoPath v1 (26% on v2) by building an LLM autoresearch agent with dual-branch search and anti-overfitting cycles.
labless.dev